Mamba-3 Explained: What’s New in the Latest State Space Model

On this page
- The motivation: inference comes first
- Change 1: a more expressive recurrence
- Change 2: complex-valued states for state tracking
- Change 3: MIMO for better hardware use
- What the results show
- How Mamba-3 compares
- Trying it yourself
- Why this matters for developers
- Mamba-3 in context: the linear-time model race
- Frequently asked questions
- Oh hi there 👋It’s nice to meet you.
- Sign up to receive awesome content in your inbox.
Mamba-3 is the newest member of the Mamba family of state space models, a type of sequence model that processes text step by step with a fixed-size memory instead of comparing every token with every other token like a transformer. It was published in March 2026 (arXiv:2603.15569) and accepted at ICLR 2026. The authors are Aakash Lahoti, Kevin Y. Li, Berlin Chen, Caitlin Wang, Aviv Bick, J. Zico Kolter, Tri Dao and Albert Gu; Gu and Dao also created the original Mamba.
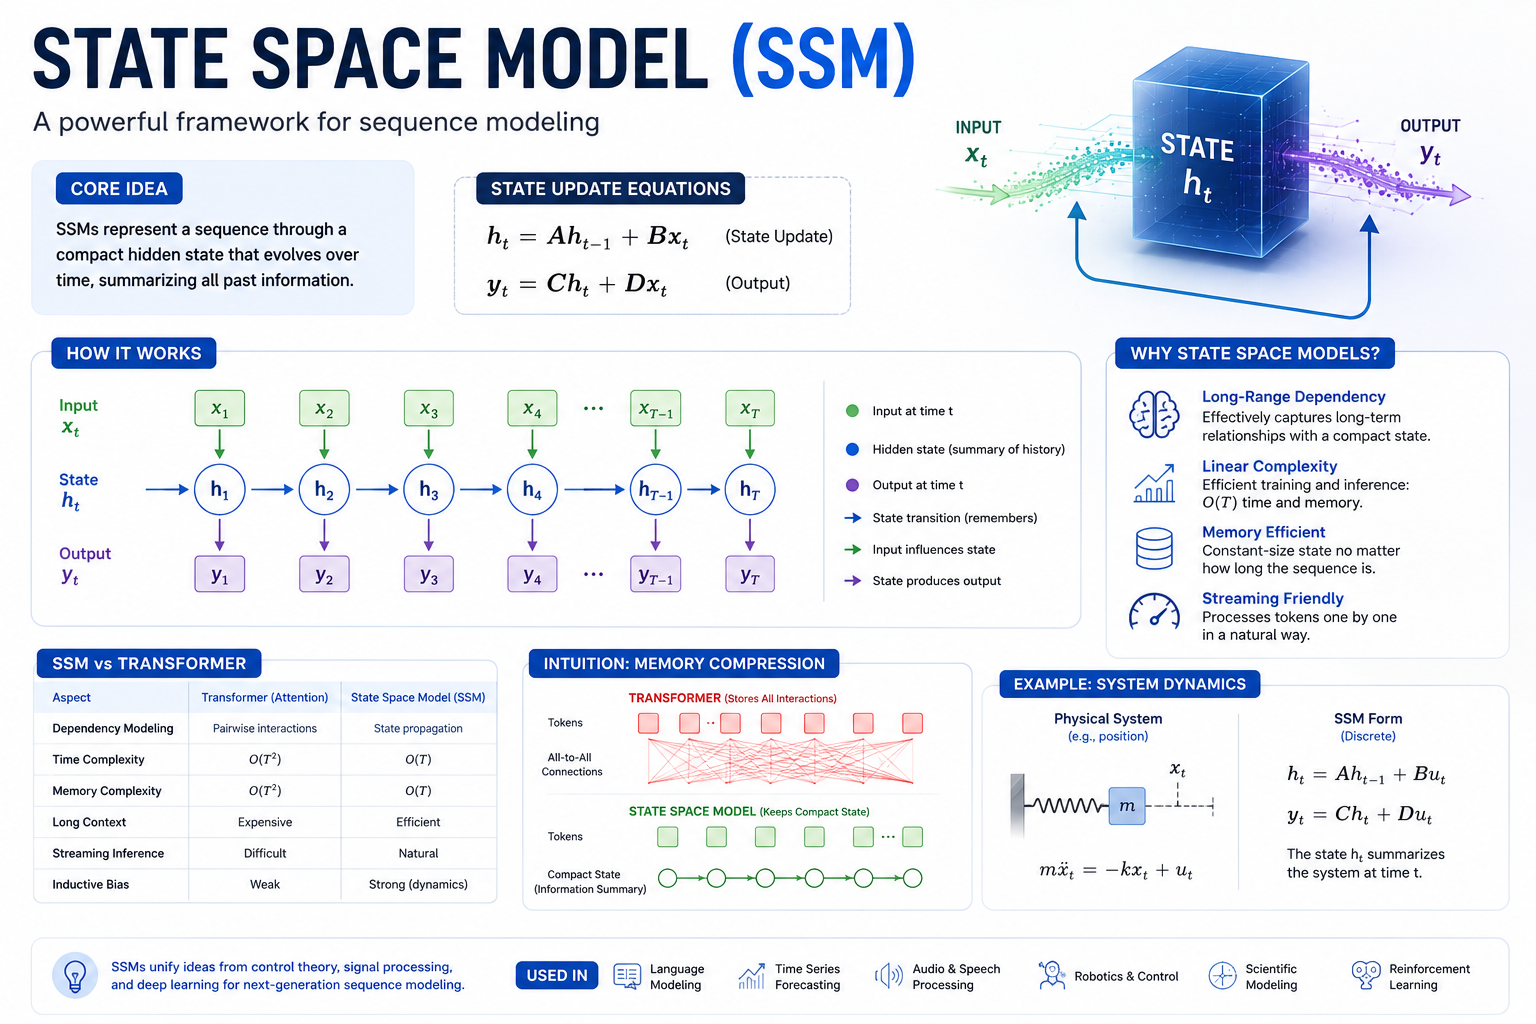
This article explains what changed and why it matters, in plain English. If state space models are new to you, read state space models explained first: it covers the basic idea of a running state, S4, Mamba and Mamba-2.
The motivation: inference comes first
Mamba-2 was designed mainly to train faster than the original Mamba, and it gave up some expressive power to get there. Since then, the way large language models are used has shifted: models increasingly spend extra computation at inference time, for example reasoning through longer outputs before answering. That makes the speed and memory cost of generating tokens a central concern.
Mamba-3 is designed around that “inference-first” view. Its authors also point out two weaknesses shared by many recent linear-time models: they often fail at state tracking (keeping an exact running account, such as whether a count is odd or even), and their theoretical speed doesn’t always translate into efficient use of real hardware during generation. Mamba-3’s three main changes target exactly these problems.
Change 1: a more expressive recurrence
A state space model is defined in continuous time and then discretized so it can process tokens one step at a time. The discretization method decides exactly how the state is updated from one token to the next. The paper shows that the update rule used by Mamba-1 and Mamba-2 corresponds to a simple numerical method, and replaces it with a more accurate one based on the trapezoidal rule, which the authors call exponential-trapezoidal discretization.
In plain terms, the new update blends information from the current step and the previous step more carefully, giving a more expressive recurrence. A practical side effect reported in the paper’s ablations: the short convolution layer that earlier Mamba models relied on becomes optional, which simplifies the architecture.
Change 2: complex-valued states for state tracking
In Mamba-2, the state changes with real-valued numbers, which can grow or decay over time but can’t naturally represent rotation or oscillation. Many simple tracking tasks are rotations in disguise. Parity, for example, flips back and forth between two states with every “1” you see, like a switch.
Mamba-3 treats the state update as complex-valued, which lets the state rotate as well as decay. The paper implements this efficiently in a form related to rotary position embeddings that depend on the data. The effect on synthetic state-tracking tasks is dramatic:
| Task (accuracy, %) | Mamba-2 | Mamba-3 |
|---|---|---|
| Parity | 0.90 | 100.00 |
| Modular arithmetic without brackets | 47.81 | 98.51 |
| Modular arithmetic with brackets | 0.88 | 87.75 |
The paper’s ablations show that the complex, data-dependent part is what matters: variants without it fail these tasks much like Mamba-2. Tasks like these are simple for people but have long been a weak spot for linear-time models, so solving them is a meaningful capability gain, not just a benchmark bump.
Change 3: MIMO for better hardware use
When a model generates text, each new token requires reading the model’s weights and state from GPU memory, while doing relatively little arithmetic. That makes generation memory-bound: the GPU’s compute units sit partly idle, waiting for data. Earlier Mamba layers are “single-input, single-output” (SISO) in how they update the state.
Mamba-3 adds a multi-input, multi-output (MIMO) variant that does more useful computation per memory access during decoding. The paper reports that this improves model quality without increasing decoding latency and without increasing the state size: it puts otherwise idle compute to work.
What the results show
The paper compares models trained in the same way at four sizes: 180M, 440M, 880M and 1.5B parameters, against a Transformer, Mamba-2 and Gated DeltaNet (another strong linear-time model). Reported highlights at the 1.5B scale:
- Mamba-3 (SISO) improves average downstream accuracy by 0.6 points over the next best baseline, Gated DeltaNet.
- Mamba-3 (MIMO) adds another 1.2 points, a 1.8-point gain over Gated DeltaNet, and the paper reports it ahead of the Transformer baseline and Mamba-2 as well.
- Mamba-3 outperforms the baselines at every model size tested.
- Half the state size: Mamba-3 MIMO with a state size of 64 matches the perplexity of Mamba-2 with a state size of 128. Since the state must be read on every generated token, a smaller state means faster generation for the same quality.
A sense of scale matters when reading these numbers. The experiments go up to 1.5 billion parameters, far smaller than today’s largest production models, and gains of one to two points on average accuracy are solid but incremental. The biggest qualitative jump is in state tracking. As with any research result, how well these gains hold at much larger scales, and in hybrid models, is something later work will show.
How Mamba-3 compares
| Transformer | Mamba-2 | Mamba-3 | |
|---|---|---|---|
| Cost per new token | Grows with context length | Constant | Constant |
| Memory while generating | Grows (KV cache) | Fixed state | Fixed state, half the size for similar quality |
| State tracking (parity and similar tasks) | Varies | Fails in the paper’s tests | Solves them |
| Exact recall of long contexts | Strong | Limited by state size | Improved retrieval reported, still limited by a fixed state |
| Main design goal | Quality | Training speed | Inference efficiency and quality |
Because a fixed-size state still can’t hold everything, many practical models combine state space layers with some attention layers. The paper itself points to hybrid architectures as a natural next step, so expect to see Mamba-3 layers inside hybrid models rather than replacing attention entirely.
Trying it yourself
The authors released code in the official state-spaces/mamba repository on GitHub, which also contains the earlier Mamba versions. The optimized kernels target NVIDIA GPUs and a Python and PyTorch environment, so the practical starting point for most developers is to follow the repository’s README with a CUDA-capable machine or a cloud GPU. For JavaScript developers, the most likely way to use models like this is through an inference server or API rather than running the kernels directly from Node.js.
When evaluating any new architecture for an application, test it on your real workload: long-document summarization, retrieval over your own data, or multi-step reasoning. Benchmark averages hide large differences between tasks.
Why this matters for developers
- Cheaper long contexts: constant-memory generation makes long conversations and documents cheaper to serve, especially when self-hosting.
- Better agents and tools: state tracking is closely related to following multi-step procedures and keeping count of what has happened, both important for agent workflows.
- More choice in models: as hybrid models built from layers like these arrive, you may see faster responses and lower costs at similar quality.
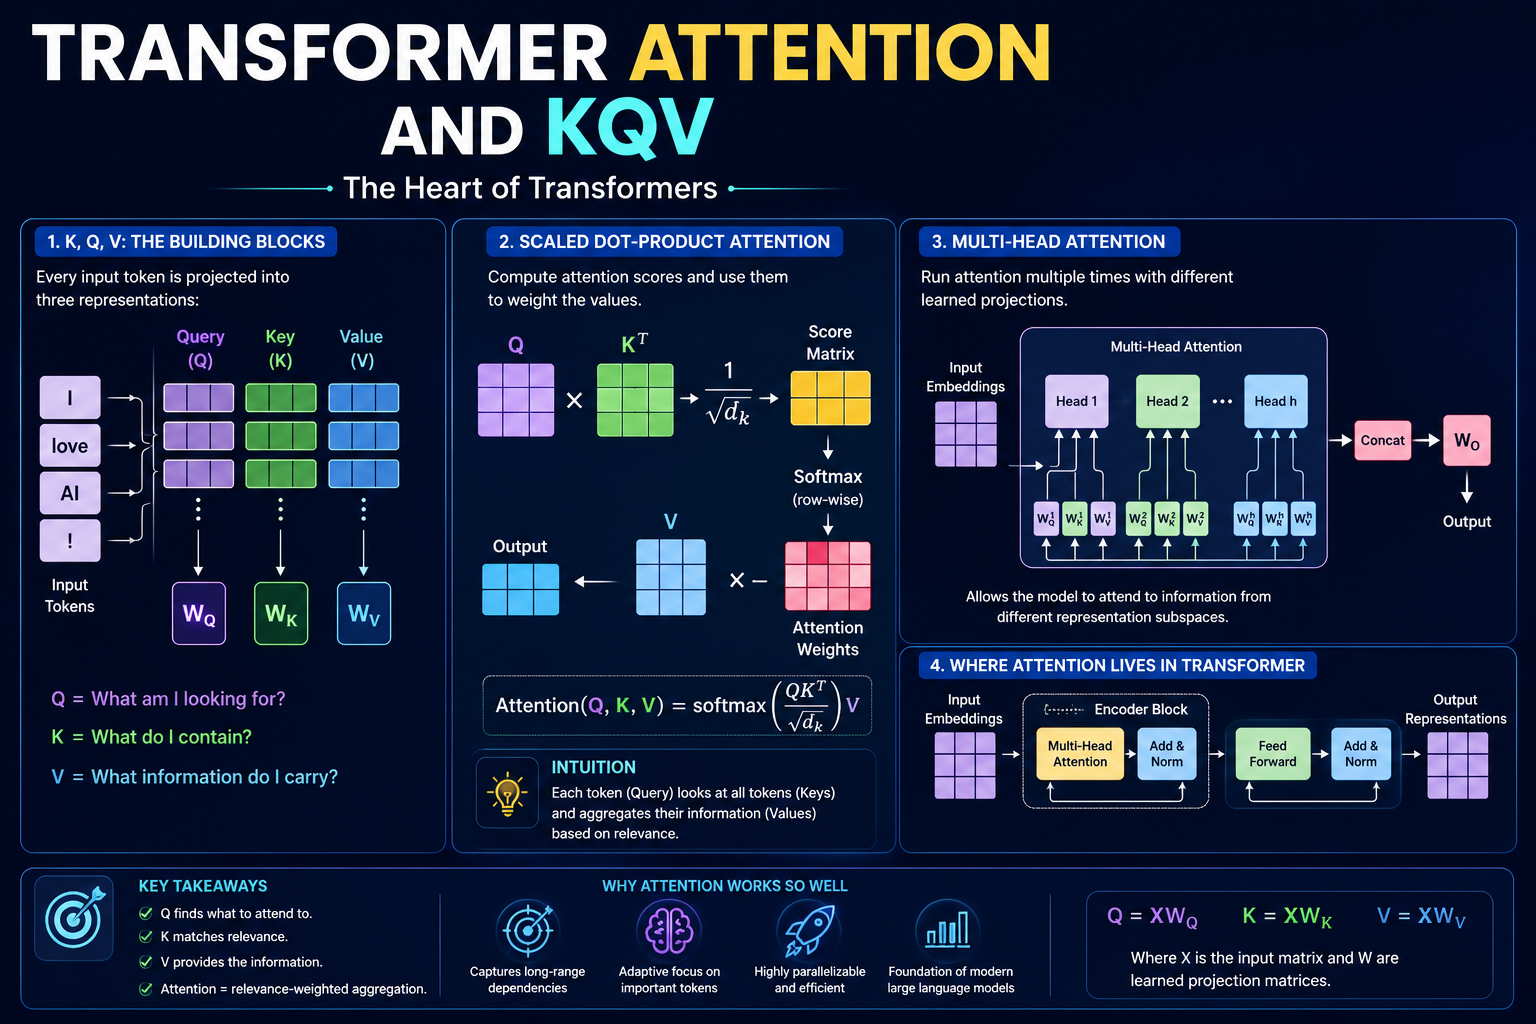
To understand the attention side of the comparison, read transformer attention explained, and for the bigger picture of AI engineering, explore the free AI Engineer Roadmap.
Mamba-3 in context: the linear-time model race
Mamba-3 is part of a broad research effort to build models whose generation cost doesn’t grow with context length. Alongside the Mamba family, this includes linear attention variants and models with learned forgetting rules such as Gated DeltaNet, the strongest baseline in the Mamba-3 paper. These approaches share the same goal, constant memory and linear-time processing, but differ in how they update their memory.
What sets Mamba-3 apart is that its improvements come from the state space view itself: a better way to discretize the underlying continuous system, a richer kind of state update, and a formulation tuned for how GPUs actually behave during generation. The paper argues these principles can carry over to other linear-time models too. For readers following the field, that is the key takeaway: progress in efficient models is now coming from careful theory and hardware awareness together, not from either alone.
Frequently asked questions
Who created Mamba-3?
Researchers Aakash Lahoti, Kevin Y. Li, Berlin Chen, Caitlin Wang, Aviv Bick, J. Zico Kolter, Tri Dao and Albert Gu. Gu and Dao were also behind the original Mamba and Mamba-2.
Is Mamba-3 better than transformers?
In the paper’s experiments up to 1.5B parameters, Mamba-3 reports higher average downstream accuracy than the Transformer baseline, with constant memory during generation. Transformers still have exact access to long contexts, which is why hybrid models combining both remain popular.
What does MIMO mean in Mamba-3?
Multi-input, multi-output. It changes how the state is updated so each generation step does more useful computation per memory access, improving quality without increasing decoding latency or state size.
Why do complex numbers help?
Complex-valued updates let the state rotate, not just grow or shrink. Many tracking tasks, such as parity, behave like rotations, so the model can represent them naturally, which earlier real-valued Mamba versions couldn’t.
Where can I read the Mamba-3 paper?
On arXiv as 2603.15569, and on OpenReview as part of ICLR 2026. The code is in the official state-spaces/mamba repository on GitHub.

Saurabh
Saurabh Pathak is an AI engineer and MERN stack developer, and the founder of mernstackdev.com. He builds open-source projects such as the Haat gateway and MCP safety tooling, and he writes hands-on tutorials on React, Node.js, MongoDB and AI agents. He cares most about code that works in production.