Transformer Attention Explained: Queries, Keys, Values and Why It Works

On this page
- The intuition: a soft lookup
- Scaled dot-product attention, step by step
- A runnable implementation
- Causal masking: no peeking at the future
- Multi-head attention
- Where attention sits in a transformer
- The cost: attention is quadratic
- The KV cache
- Modern attention variants
- Why this matters for application developers
- Frequently asked questions
- Oh hi there 👋It’s nice to meet you.
- Sign up to receive awesome content in your inbox.
Attention is the core idea behind transformers, the architecture that powers modern language models. Before transformers, models read text one word at a time and struggled to connect words far apart. Attention lets every word look at every other word at once and decide which ones matter for understanding it. In “The trophy didn’t fit in the suitcase because it was too big”, attention is how a model links “it” to “trophy” rather than “suitcase”.
This guide explains attention step by step, with a small working implementation in JavaScript you can run, and then covers the variants used in today’s models. For animated, step-by-step visuals of the same ideas, see the self-attention lesson in the AI Engineer Roadmap.
The intuition: a soft lookup
Think of a library search. You bring a query (what you are looking for). Each book has a key (its label) and a value (its contents). A normal lookup returns the single book whose key matches exactly. Attention is a soft lookup: it compares your query with every key, gives each book a relevance weight, and returns a blend of all the values, mostly from the most relevant books.
In a transformer, every token plays all three roles. Each token’s vector is multiplied by three learned weight matrices to produce:
| Vector | Question it answers |
|---|---|
| Query (Q) | What am I looking for? |
| Key (K) | What do I contain, for others searching? |
| Value (V) | What information do I pass on if someone attends to me? |
The roadmap lesson Q, K and V explained from scratch builds these with real numbers.
Scaled dot-product attention, step by step
The whole mechanism fits in one formula: Attention(Q, K, V) = softmax(Q·Kᵀ / √d) · V. In words:
- Score: for each token, take the dot product of its query with every token’s key. A large dot product means the vectors point in similar directions: high relevance.
- Scale: divide the scores by the square root of the vector size
d. Without this, scores grow with the dimension, softmax becomes extremely peaked, and training becomes unstable. - Softmax: turn each row of scores into weights between 0 and 1 that add up to 1.
- Mix: each token’s output is the weighted average of all the value vectors.
A runnable implementation
Here is attention for a tiny three-token example in plain JavaScript, with no libraries:
// attention.js  (run with: node attention.js)
const dot = (a, b) => a.reduce((sum, x, i) => sum + x * b[i], 0);

function softmax(row) {
  const max = Math.max(...row);                 // subtract the max for numerical stability
  const exps = row.map((x) => Math.exp(x - max));
  const total = exps.reduce((a, b) => a + b, 0);
  return exps.map((e) => e / total);
}

function attention(Q, K, V, { causal = false } = {}) {
  const d = K[0].length;
  return Q.map((q, i) => {
    const scores = K.map((k, j) => (causal && j > i ? -Infinity : dot(q, k) / Math.sqrt(d)));
    const weights = softmax(scores);
    const output = V[0].map((_, col) => weights.reduce((sum, w, j) => sum + w * V[j][col], 0));
    return { weights, output };
  });
}

// three tokens, vectors of size 2 (real models use hundreds or thousands)
const Q = [[1, 0], [0, 1], [1, 1]];
const K = [[1, 0], [0, 1], [1, 1]];
const V = [[10, 0], [0, 10], [5, 5]];

attention(Q, K, V).forEach(({ weights, output }, i) => {
  console.log(`token ${i}: weights`, weights.map((w) => w.toFixed(2)).join(' '), '→ output', output.map((x) => x.toFixed(2)).join(' '));
});
Running it prints each token’s attention weights and its new vector:
token 0: weights 0.40 0.20 0.40 → output 6.02 3.98
token 1: weights 0.20 0.40 0.40 → output 3.98 6.02
token 2: weights 0.25 0.25 0.50 → output 5.00 5.00
Token 0’s query matches its own key and token 2’s key best, so it takes most of its information from them. Every output is a context-aware blend: each token now carries information from the tokens most relevant to it. In a real model, the queries, keys and values come from learned weight matrices, and training adjusts those matrices so that useful relationships, such as a pronoun and its noun, produce high scores.
Causal masking: no peeking at the future
Language models generate text one token at a time, so during training a token must not see the tokens after it, or the model would learn to cheat. A causal mask sets the scores for future positions to negative infinity before softmax, which turns their weights into zero. In the code above, calling attention(Q, K, V, { causal: true }) does exactly this: token 0 can only attend to itself, token 1 to tokens 0 and 1, and so on.
Multi-head attention
One attention operation captures one kind of relationship at a time. Multi-head attention runs several attention “heads” in parallel, each with its own query, key and value matrices, on smaller slices of the vector. One head might follow grammatical structure, another track which noun a pronoun refers to, another notice nearby words. Their outputs are joined and mixed by one more learned matrix.
The heads don’t cost much more than a single large attention operation, because each one works on a smaller vector. More detail is in the roadmap lesson on multi-head attention, and how attention fits with the rest of each layer is shown in inside a transformer block.
Where attention sits in a transformer
A transformer is a stack of identical blocks. Each block has an attention layer, where tokens exchange information, followed by a feed-forward layer, where each token processes what it gathered on its own. Residual connections and normalization keep training stable through dozens of stacked blocks. Because attention itself ignores word order, models add positional information, such as rotary position embeddings, so that “dog bites man” differs from “man bites dog”.
The cost: attention is quadratic
Every token attends to every other token, so the number of scores grows with the square of the sequence length. Doubling the context from 4,000 to 8,000 tokens means four times as many attention scores. This is the main reason long contexts are expensive, and why so much research targets more efficient attention.
The KV cache
When generating text, a model produces one new token at a time. Recomputing keys and values for all previous tokens at every step would be wasteful, so inference engines store them in a KV cache and only compute the new token’s query, key and value. This makes generation much faster, but the cache grows with every token and every layer, so long conversations need a lot of GPU memory.
Modern attention variants
| Variant | Idea | Benefit |
|---|---|---|
| FlashAttention | Computes exactly the same attention, but in GPU-friendly tiles that avoid storing the full score matrix in slow memory | Much faster and more memory-efficient, with identical results |
| Multi-query attention (MQA) | All heads share one set of keys and values | A far smaller KV cache, faster generation |
| Grouped-query attention (GQA) | Groups of heads share keys and values: a middle ground between multi-head and MQA | Most of MQA’s savings with less quality loss |
| Sliding-window attention | Each token attends only to a fixed window of recent tokens | Cost grows linearly with length |
| Sparse and linear attention | Approximate full attention with fewer comparisons | Longer contexts at lower cost, sometimes with lower quality |
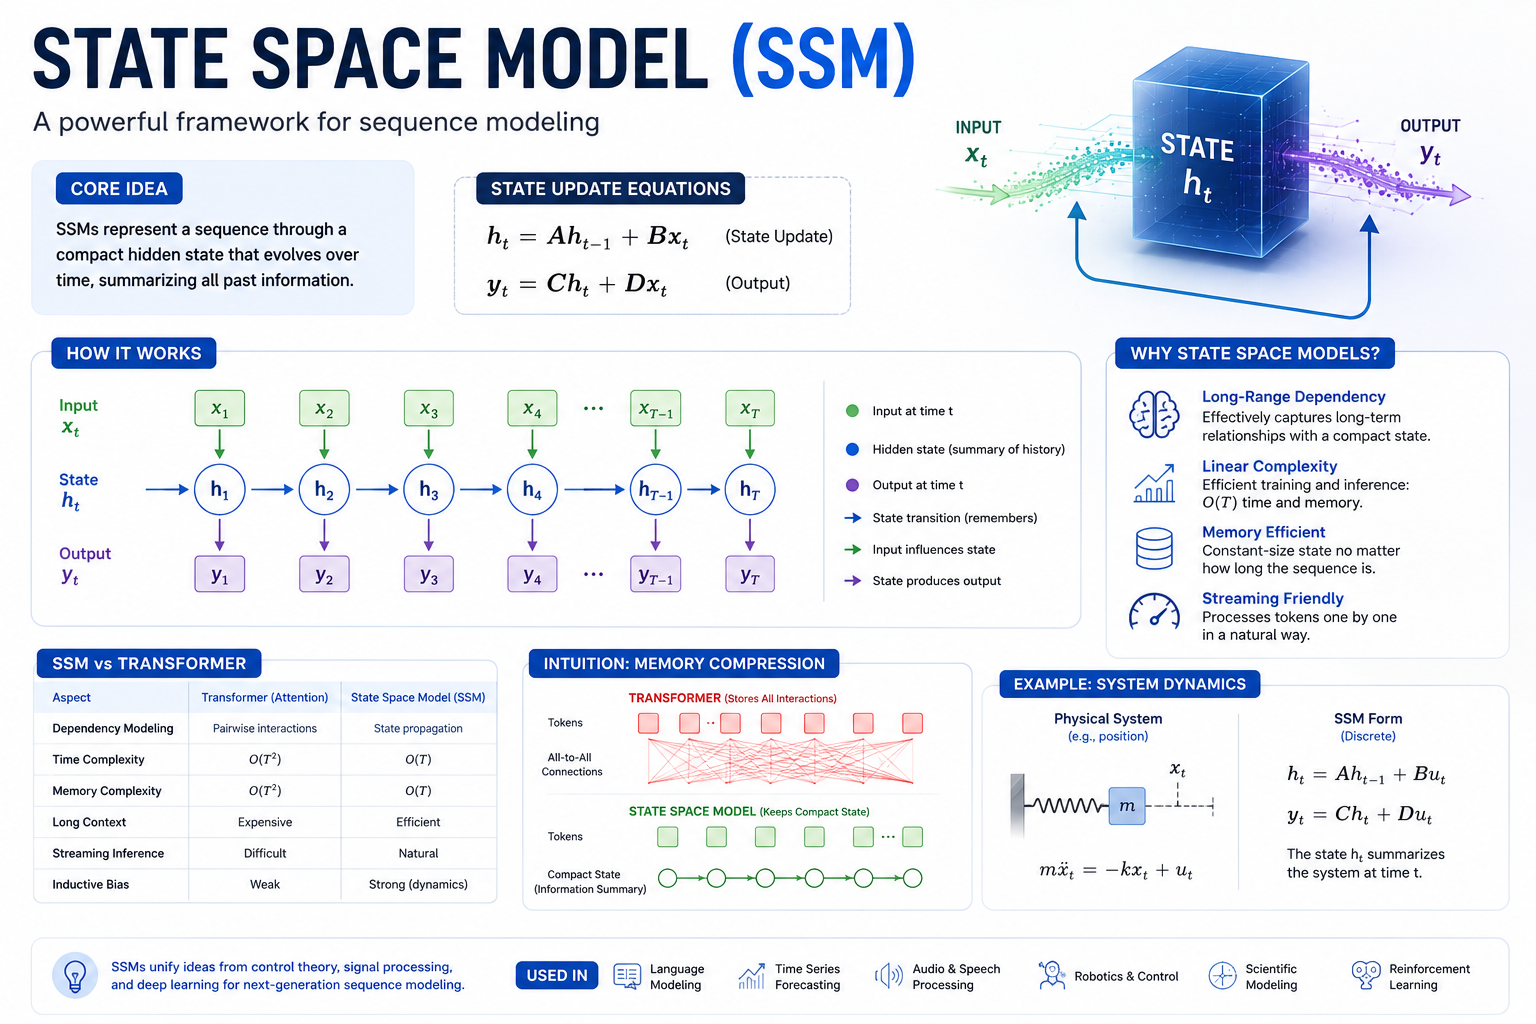
Alternatives that replace attention altogether, such as state space models, are covered in state space models explained. The roadmap’s modern attention variants lesson animates the differences.
Why this matters for application developers
You don’t need to implement attention to build AI apps, but understanding it explains everyday behavior. Long prompts cost more and respond slower because of the quadratic cost and the KV cache. Models can miss facts buried in the middle of very long inputs, which is one reason retrieval systems send only the most relevant chunks, as in hybrid search for RAG. And context window limits exist because memory and compute grow with every token.
Frequently asked questions
What is the difference between self-attention and cross-attention?
In self-attention, queries, keys and values all come from the same sequence. In cross-attention, queries come from one sequence and keys and values from another, for example a translation model’s output attending to the input sentence.
Why divide by the square root of the dimension?
Dot products of longer vectors produce larger numbers, which push softmax towards giving almost all weight to one token and make gradients tiny. Dividing by √d keeps scores in a range where training stays stable.
Does attention show what a model is “thinking”?
Only partly. Attention weights show where information flows, but many layers and heads interact, so a single attention map rarely explains a model’s output on its own.
Why is it called attention?
Because each token decides how much to “pay attention” to every other token, focusing on some and mostly ignoring others, much like how people focus on the relevant words when reading.
How many attention heads do real models use?
It varies by model size, from a handful in small models to dozens per layer in large ones, across dozens of layers. With grouped-query attention, many query heads share a smaller number of key and value heads to save memory.

Saurabh
Full-stack developer writing practical guides on the MERN stack, AI and DevOps. Every code sample on this site is tested before it is published.